
Presentation
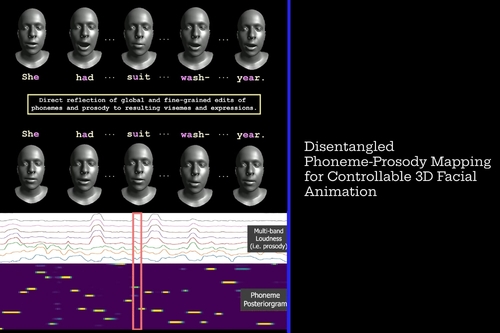
9. Disentangled Phoneme-Prosody Mapping for Controllable 3D Facial Animation
DescriptionSpeech driven 3D face animation driven by disentangled phoneme and prosody features, enabling fine-grained and intuitive control over visemes and expressions—uses a convolutional autoencoder to learn a relative motion prior and a transformer to map these interpretable audio features into latent deformations.
Event Type
Poster
TimeMonday, 11 August 20259:00am - 5:30pm PDT
LocationWest Building, Level 2, Outside Room 219
Session TimeSunday, 10 August 20259:00am - 5:30pm PDTMonday, 11 August 20259:00am - 5:30pm PDTTuesday, 12 August 20259:00am - 5:30pm PDTWednesday, 13 August 20259:00am - 5:30pm PDTThursday, 14 August 20259:00am - 5:30pm PDT
LocationWest Building, Level 2, Outside Room 219
